GEO guide
How AI Engines Choose What to Cite: The Retrieval Pipeline Explained (2026)
TL;DR
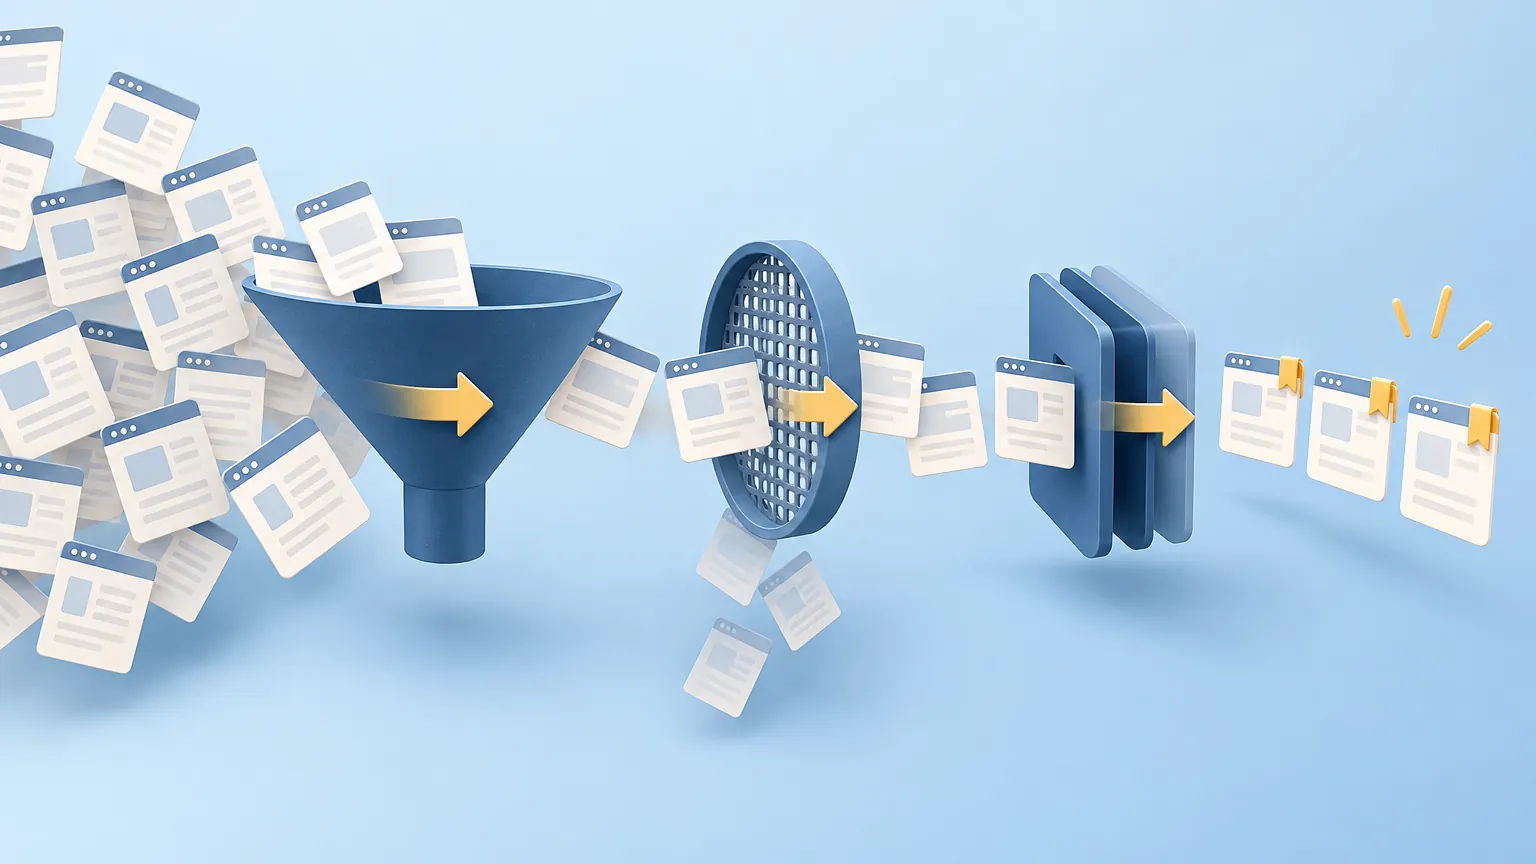
AI search that retrieves web pages fits a simplified four-stage model: (1) crawl — if the crawlers an engine uses for search can't fetch your pages, those pages can't be cited (Google's AI features use Googlebot and its Search index); (2) chunk — many engines split pages into passages, so we write self-contained sections that each answer one question (Google says its AI features need no special chunking); (3) retrieve — passages compete on relevance to the question, and question-style headings and answer-first writing help; (4) select — among retrieved passages, topical relevance and context position are the most reproducible levers. Engines use different indexes and selection methods, so their citations overlap little: only ~11% of cited domains overlap between ChatGPT and Perplexity (Profound, 2025). On position, 44.2% of ChatGPT citations come from the first 30% of a page's text (Kevin Indig, Growth Memo, February 2026).
Updated October 18, 2026: We sourced and dated every statistic, replaced the unsourced "~11% of sites" and "Perplexity cites the most" claims with Profound, Growth Memo and Semrush data, and fixed the link behind the 44.2% figure. We separated the "Lost in the Middle" study from page-position data, rewrote the crawl stage around the three crawler roles and dropped our fixed section-size figure. The September 25 update had already relabeled Princeton's 2023 GEO-Bench gains as a result that did not hold on 2026 engines and noted that Google's AI features need no special chunking or schema: why the GEO evidence changed.
Most retrieval-based AI search fits a useful simplified model of four stages: crawl, chunk, retrieve, select. Understand what each stage rewards and most GEO techniques stop looking like tricks and start looking like plain engineering. This is the mental model behind much of our GEO guide, and part of the reason seemingly similar websites get very different citation results. Google's AI Overviews and AI Mode are a partial exception: Google says they rely on its core Search ranking systems to retrieve pages from its regular Search index (Google's AI optimization guide).
Stage 1: Crawl — can the engine read you at all?
If the crawlers an engine uses for search can't fetch your pages, those pages can't be retrieved or cited as a source. The engine may still mention your business based on what other sites say. For Google's AI Overviews and AI Mode, the crawler that matters is Googlebot and normal Search indexing, not a separate AI crawler.
Crawlers that feed AI answers play three roles, and mainly two of them matter for citations (details in our robots.txt guide for AI crawlers):
- Search and indexing crawlers (OAI-SearchBot, Claude-SearchBot and PerplexityBot, plus Googlebot, Bingbot and Applebot) build the indexes AI search retrieves from. OpenAI says sites opted out of OAI-SearchBot "will not be shown in ChatGPT search answers, though can still appear as navigational links" (OpenAI).
- User-initiated fetchers (ChatGPT-User, Claude-User and Perplexity-User) fetch a page live when someone asks. OpenAI says robots.txt rules "may not apply" to ChatGPT-User (OpenAI), Perplexity says Perplexity-User "generally ignores robots.txt rules" (Perplexity), and Anthropic says its bots honor robots.txt directives; disabling Claude-User stops retrieval of your content for user queries (Anthropic).
- Training crawlers and tokens (GPTBot, ClaudeBot and Applebot-Extended) are a separate business decision that search citations don't depend on. OpenAI says "Each setting is independent of the others" (OpenAI), so you can block GPTBot and still appear in ChatGPT search. Google-Extended is the exception: Google says it controls Gemini training and also grounding in Gemini Apps, so blocking it can keep your pages out of Gemini app answers, though it "does not impact a site's inclusion in Google Search" (Google).
Three common failure points:
- robots.txt blocks, sometimes inherited accidentally from a security plugin.
- CDN-level blocking. Robots.txt only states a preference that crawlers follow voluntarily (Cloudflare docs). Cloudflare's AI Crawl Control can actually block individual AI crawlers with a firewall (WAF) rule, whatever robots.txt says (Cloudflare docs). Since September 15, 2026, Cloudflare offers new ad-supported domains a recommended configuration that sets "Disallow AI Training" (which blocks training-only crawlers, such as OpenAI's GPTBot) and blocks Agent bots (live "chat fetch bots") on pages with ads; search crawlers such as Googlebot and Bingbot stay allowed, and site owners can change these settings (Cloudflare, September 15, 2026).
- JavaScript-only rendering. Vercel's December 2024 analysis found that OpenAI, Anthropic and Perplexity crawlers did not execute JavaScript (Vercel), Anthropic says Claude's web fetch tool does not support sites rendered dynamically with JavaScript (Anthropic docs), and Google warns that "not all bots can run JavaScript" (Google Search Central). A crawler that doesn't execute JavaScript misses content that only appears after JavaScript runs (Googlebot renders JavaScript; some AI crawlers do not).
What this stage rewards: not blocking the search crawlers and user-initiated fetchers of the engines you want to be cited by. In practice:
- Add an explicit Allow line only when a broader Disallow would catch them.
- Check your CDN's AI-crawler settings (on Cloudflare, the Search, Agent and Training options).
- Check the robots.txt your site actually serves, since Cloudflare's Bot Preference Sync can write those preferences into it (Cloudflare).
- Render your main content on the server.
- Check your server logs monthly to confirm search bots actually visit.
Stage 2: Chunk — how does your page get split into passages?
Many AI engines do not index your page as one unit — they split it into chunks, and each chunk lives or dies alone. Retrieval systems typically segment by structure: headings, paragraphs, length thresholds. As a rough illustration, not a measured figure, a 2,000-word page might end up as something like 6–10 passages.
For engines that chunk, this is where many websites lose without knowing it. A section that starts with "As we mentioned above..." produces a chunk that makes no sense in isolation — hard to retrieve regardless of quality. A 900-word wall of text gets split at arbitrary points, orphaning key claims from their evidence.
What this stage rewards: controlling your own chunk boundaries. Our rule of thumb is self-contained sections, each answering one question under a question-style heading and opening with its conclusion; there is no fixed word count. You are pre-chunking your content so a retrieval system cannot mangle it.
One caveat: chunking is a step in many AI retrieval systems, not a Google requirement. Google's AI optimization guide (updated July 10, 2026) says "there's no requirement to break your content into tiny pieces" for its AI features. Self-contained sections still help readers and may help other engines extract a clean passage, so treat this as good editing, not a Google lever.
Stage 3: Retrieve — does your passage match the query?
When a user asks, the engine searches its index for the passages most relevant to that question — relevance to the question is what counts. Headings that mirror real questions make a section's topic explicit to readers and to retrieval systems. A heading that reads "How much does a bilingual website cost in California?" states exactly what the section answers. A heading that reads "Pricing" does not.
Position is a separate question, and two different kinds of evidence often get mixed up here. The "Lost in the Middle" study (Liu et al., arXiv 2023, published in TACL) found that language models answered multi-document questions and key-value lookups best when the relevant information sat at the beginning or end of their input context, and significantly worse when it sat in the middle. It measured position within the model's input, not within a web page, and it tested 2023-era models.
ChatGPT citation data points to a related pattern: citations cluster near the top of pages. In a Growth Memo analysis by Kevin Indig (February 16, 2026) of 1.2 million ChatGPT search results with 18,012 verified citations, 44.2% of ChatGPT citations came from the first 30% of a page's text, 31.1% from the middle (30-70%) and 24.7% from the final 30%: a steadily declining "ski ramp", not a U-shape (figures as summarized by ALM Corp, since the original is for paid subscribers). It is observational and covers ChatGPT only.
What this stage rewards: headings phrased as the questions your buyers ask, answer-first sentences under each heading, and the thesis and key statistic in the first 200 words. A short restated takeaway at the end still helps readers, but the citation data above does not show it as a citation lever.
Stage 4: Select — why does the model quote one passage over another?
Among retrieved candidates, topical relevance and context position are the most reproducible levers. A July 2026 critical survey of 45 GEO studies (Martinez, arXiv 2607.14035, preprint) concluded that topical relevance and context position (position among the documents already in the model's input, not position on your page) are the most reproducible levers. The 2023 GEO paper by Aggarwal et al. (Princeton and co-authors; arXiv 2311.09735, KDD 2024) reported that adding quotations, statistics and source citations raised a source's visibility in generated answers by roughly 30-40% (a relative gain on its position-adjusted word count metric) on its GEO-bench benchmark. The survey notes those gains were measured only for sources already present in a fixed context, so they show neither organic discoverability nor durable traffic effects. And a September 2026 preprint (Bajemon & Rochet, arXiv 2609.07559) re-measured those three levers on ten current engine families, including three GPT-5.x models, and found they moved citation on none of them. Keep sourced statistics and named experts for credibility, not as a citation promise. As for keyword stuffing, the 2023 paper found it pushed its main visibility metric below the no-optimization baseline, and the 2026 survey rates it "null or negative" across benchmarks.
Clear entity information (a consistent business name and address, named authors, public profiles, schema) may help engines identify and tell apart your business, but no reliable study we know of shows that it raises citation odds by itself. Schema makes those entity facts explicit, but it is not a citation lever on its own: Ahrefs (May 11, 2026) tracked 1,885 pages that added JSON-LD schema between August 2025 and March 2026 against 4,000 control pages and found no major citation uplift: AI Overviews citations fell 4.6% (statistically significant), while the AI Mode (+2.4%) and ChatGPT (+2.2%) changes were not. Every page studied had at least 100 AI Overview citations in February 2025, so the result may not apply to pages that are not yet cited in AI Overviews. Google also says its AI features need no special schema, though structured data still helps pages qualify for rich results. Brand mentions across the web are associated with AI visibility: in Ahrefs' study of 75,000 brands (May 2025), branded web mentions correlated with brand mentions in Google AI Overviews about three times more strongly than backlinks did (Spearman 0.664 vs 0.218), and a December 2025 update found similarly strong correlations for branded web mentions in ChatGPT and AI Mode. That is a correlation with brands being mentioned in AI answers, not with citations of their pages, and it does not show that one causes the other.
Why do different engines cite different sites?
Engines use different indexes and selection methods, so their citations overlap little. In a Profound analysis of 100,000 prompts (July 2025), only 11% of the domains cited appeared in both ChatGPT and Perplexity; a May 2026 Growth Memo analysis of a 20,000-prompt sample found that 91% of cited URLs showed up in only one of ChatGPT, Perplexity or Google AI Overviews for the same prompt (Omnia monitoring data weighted toward Spain and other European markets, which Indig says to treat as directional for European AI search).
The sources behind each engine differ. As of September 2026, ChatGPT search can send follow-up queries to other search providers (OpenAI Help Center) and recommends that sites allow its OAI-SearchBot crawler (OpenAI); Gemini Apps ground answers in content from the Google Search index (Google); and Anthropic says every web-search response includes citations (Claude Help Center). Citation counts depend on the engine and on how they are counted: in Profound's July 2025 analysis, Perplexity cited about 7.3 domains per response versus about 5.0 for ChatGPT and 7.7 for Google AI Overviews, while Semrush's 2026 AI Visibility Index (126 million US prompts, January-April 2026) found ChatGPT citing an average of 15 sources per response and Gemini an average of 3. For engine-by-engine detail, see our platform citation playbook.
The practical consequence: get the shared basics right (crawl access, clear self-contained sections, relevance to real questions), then measure each engine separately, because results differ. Prioritize engines by how much people actually use them: in Similarweb data reported on September 7, 2026, ChatGPT had 55.5% of visits to generative-AI chatbot websites, Gemini 25.6%, Claude 9.3% and Perplexity 0.9% (Similarweb via The Decoder, September 7, 2026; website traffic only, apps excluded).
Crawlable, chunkable, retrievable, citable — that is the order the stages run in. Review your site stage by stage and the gaps become a prioritized to-do list: fix crawl access first, then relevance and phrasing (answer the questions your buyers actually ask, in their words), then structure, then authority. No one can guarantee a citation, but that sequence covers the basics most GEO advice builds on.
If you want an outside view of how clearly search engines and AI systems can find and interpret your business, request a visibility assessment: before any work begins, we reply with a fit recommendation, the scope and the fee. The form sends a request; it does not generate an automated audit. Request a visibility assessment.
- GEO
- RAG
- AI Search
- ChatGPT
- Perplexity
- Technical
Frequently asked questions
What is RAG and why does it matter for getting cited by AI?
RAG (Retrieval-Augmented Generation) is the approach many AI engines use to answer with web content: they retrieve relevant passages from an index, then generate an answer citing some of them. Most GEO techniques map to a stage of this simplified model: crawl access, chunk-friendly structure, relevance to real questions, and clear entity information. Google says its AI features rely on its core Search ranking systems to retrieve pages from its regular Search index.
Why does the same question give different citations each time I ask an AI?
Because generation is probabilistic and retrieval often returns more candidates than the answer can cite, so small variations change which retrieved passages make the final cut. This is why we recommend running each prompt at least 3 times (our own minimum, not a research standard) and recording a hit rate (such as 2 of 3) instead of a single yes/no. A July 2026 survey of 45 GEO studies reports, citing Kirsten et al. (2026), that repeated runs at temperature zero changed 9-28% of decisions where temperature could be controlled, and cites a proposal of seven to eight repetitions per prompt as a starting point, based on a small set of Swiss queries (Martinez, arXiv 2607.14035, preprint). It is also why no one can guarantee a specific citation.
Why do ChatGPT and Perplexity cite such different websites?
Different indexes and different selection methods. As of September 2026, ChatGPT search can send follow-up queries to other search providers; Gemini grounds answers in the Google Search index. Citation counts differ too: in Profound's 100,000-prompt analysis (July 2025), Perplexity cited about 7.3 domains per response, ChatGPT about 5.0 and Google AI Overviews about 7.7. Only ~11% of cited domains overlap between ChatGPT and Perplexity (Profound, 2025), so measure each engine separately and prioritize by actual use: in Similarweb data reported on September 7, 2026, Perplexity had 0.9% of visits to generative-AI chatbot websites vs 55.5% for ChatGPT (Similarweb via The Decoder, September 7, 2026; website traffic only).
What is the "Lost in the Middle" problem and how do I use it?
It is a 2023 finding (Liu et al., arXiv 2307.03172, published in TACL) that language models answered questions best when the relevant information sat at the beginning or end of their input context, and worse when it sat in the middle. It measured position inside the model's input, not on a web page, so it is not proof about page layout. A separate observation points to the top of the page: in a Kevin Indig analysis of 1.2 million ChatGPT search results, 44.2% of ChatGPT citations came from the first 30% of a page's text and 24.7% from the final 30%, a declining pattern rather than a U-shape (Growth Memo, February 16, 2026). So put the thesis and key statistic in the first 200 words; a restated takeaway at the end helps readers but is not a proven citation lever.
Do AI engines verify facts before citing a source?
The data does not measure whether engines check sources before citing them. It does show that AI answers still get facts wrong: in Profound's analysis of more than 158,000 AI-answer claims from its FactCheck tool (snapshot as of August 14, 2026), inaccuracy rates by answer engine ranged from 4.3% to 6.8%, and 54% of brands had at least one inaccurate claim that cited their own content. Keep your claims specific, attributed and consistent for credibility and accuracy, not as a citation lever. Never fabricate data: it is unethical, and Google's spam policies (updated August 28, 2026) include attempts to manipulate generative AI responses in Google Search.
This article was drafted with AI assistance and is published under our AI use policy.